G01
Open-CHOIRSpoon B
Unable to play inline. Open video.
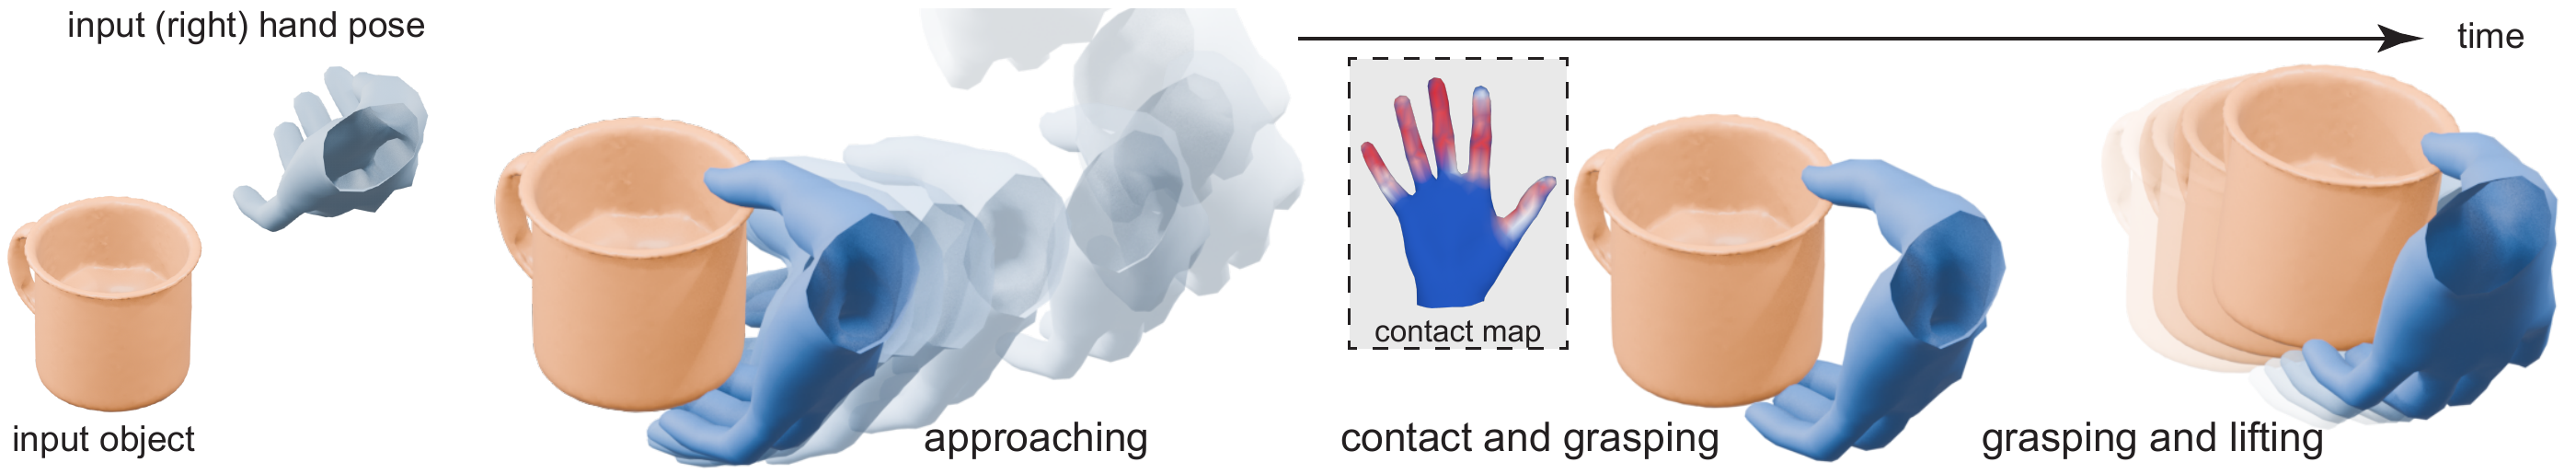
Synthesizing believable 4D hand–object grasping sequences is important for character animation, extended reality, and embodied agents. Grasping requires a hand to approach, contact, and lift or manipulate an object coherently. Existing synthesis methods often model only the final static grasp or rely on additional conditions, such as language, target grasps, or object trajectories, to specify the interaction. We instead study the underconstrained problem of generating a complete grasping motion from a single initial hand–object state. Our framework decouples hand-motion generation from object-motion recovery. Given an object point cloud in the initial wrist frame and the initial parameterized hand configuration, conditional flow matching predicts a sequence-level contact map and a hand pose at each normalized sequence time. This time-indexed formulation avoids the error accumulation of autoregressive rollout while representing the complete motion. We then infer an attachment frame and recover rigid-object motion through training-free, contact-guided weighted registration. We evaluate on held-out DexYCB objects and unseen object geometries reconstructed from in-the-wild videos by Open-CHOIR. Compared with LatentHOI, our method produces smoother hand and object motion in every setting, matches or improves on its contact and penetration metrics in the wild under a shared initialization, and is about 30× faster per generated frame. In a 15-participant study, our motions were preferred in roughly two thirds of (forced-choice pairwise) comparisons. Precise contact closure on novel geometry, however, remains a key open challenge. Code will be released.
01 / Generated motions
Approach, finger closure, and post-grasp motion on held-out DexYCB objects and unseen Open-CHOIR reconstructions. Each video shows the complete sequence from two synchronized viewpoints.
Unable to play inline. Open video.
Unable to play inline. Open video.
Unable to play inline. Open video.
Unable to play inline. Open video.
Unable to play inline. Open video.
Unable to play inline. Open video.
Unable to play inline. Open video.
Unable to play inline. Open video.
Unable to play inline. Open video.
Unable to play inline. Open video.
Unable to play inline. Open video.
Unable to play inline. Open video.
Unable to play inline. Open video.
Unable to play inline. Open video.
Unable to play inline. Open video.
Unable to play inline. Open video.
Unable to play inline. Open video.
Unable to play inline. Open video.
Unable to play inline. Open video.
Unable to play inline. Open video.
GT initialization uses the annotated first-frame hand pose; Open-CHOIR reconstructions provide pseudo-ground truth. Blue: hand. Orange: object. Videos include all 65 sequence frames, with brief holds at the beginning and end.
02 / Qualitative comparison
The eight scenes from the main paper and eight additional scenes are shown below. DexGraspNet, LatentHOI, and ours are shown side by side with synchronized overall and side/contact views. DexGraspNet interpolates to a static grasp and holds its final pose; LatentHOI and ours generate motion.
This is a task-level comparison: LatentHOI uses object geometry and a text prompt, without the observed initial hand pose. The videos share a displayed starting configuration. Enlarge a video to inspect contact and finger motion.
03 / Sampling diversity
Three generated samples share the same initial configuration for each object, illustrating variation in the resulting grasping motions. Replay a row together to compare the samples over time.
Unable to play inline. Open video.
Unable to play inline. Open video.
Unable to play inline. Open video.
Unable to play inline. Open video.
Unable to play inline. Open video.
Unable to play inline. Open video.
Unable to play inline. Open video.
Unable to play inline. Open video.
Unable to play inline. Open video.
04 / Failure cases
Incorrect trigger-frame selection, sensitivity to the starting hand pose, and thin or small objects can lead to incomplete closure, penetration, or implausible object motion. The teacup pair includes both a successful and an unsuccessful initialization.
Unable to play inline. Open video.
Unable to play inline. Open video.
Unable to play inline. Open video.
Unable to play inline. Open video.
The recovered object motion uses a fixed rigid attachment, which excludes sliding, regrasping, release, and articulated or deformable objects. Geometric attachment does not guarantee stability under gravity or external forces.